TAMPAgentAgentic Belief-Space Planning for Mobile Manipulation
Anonymous Authors
October 2026
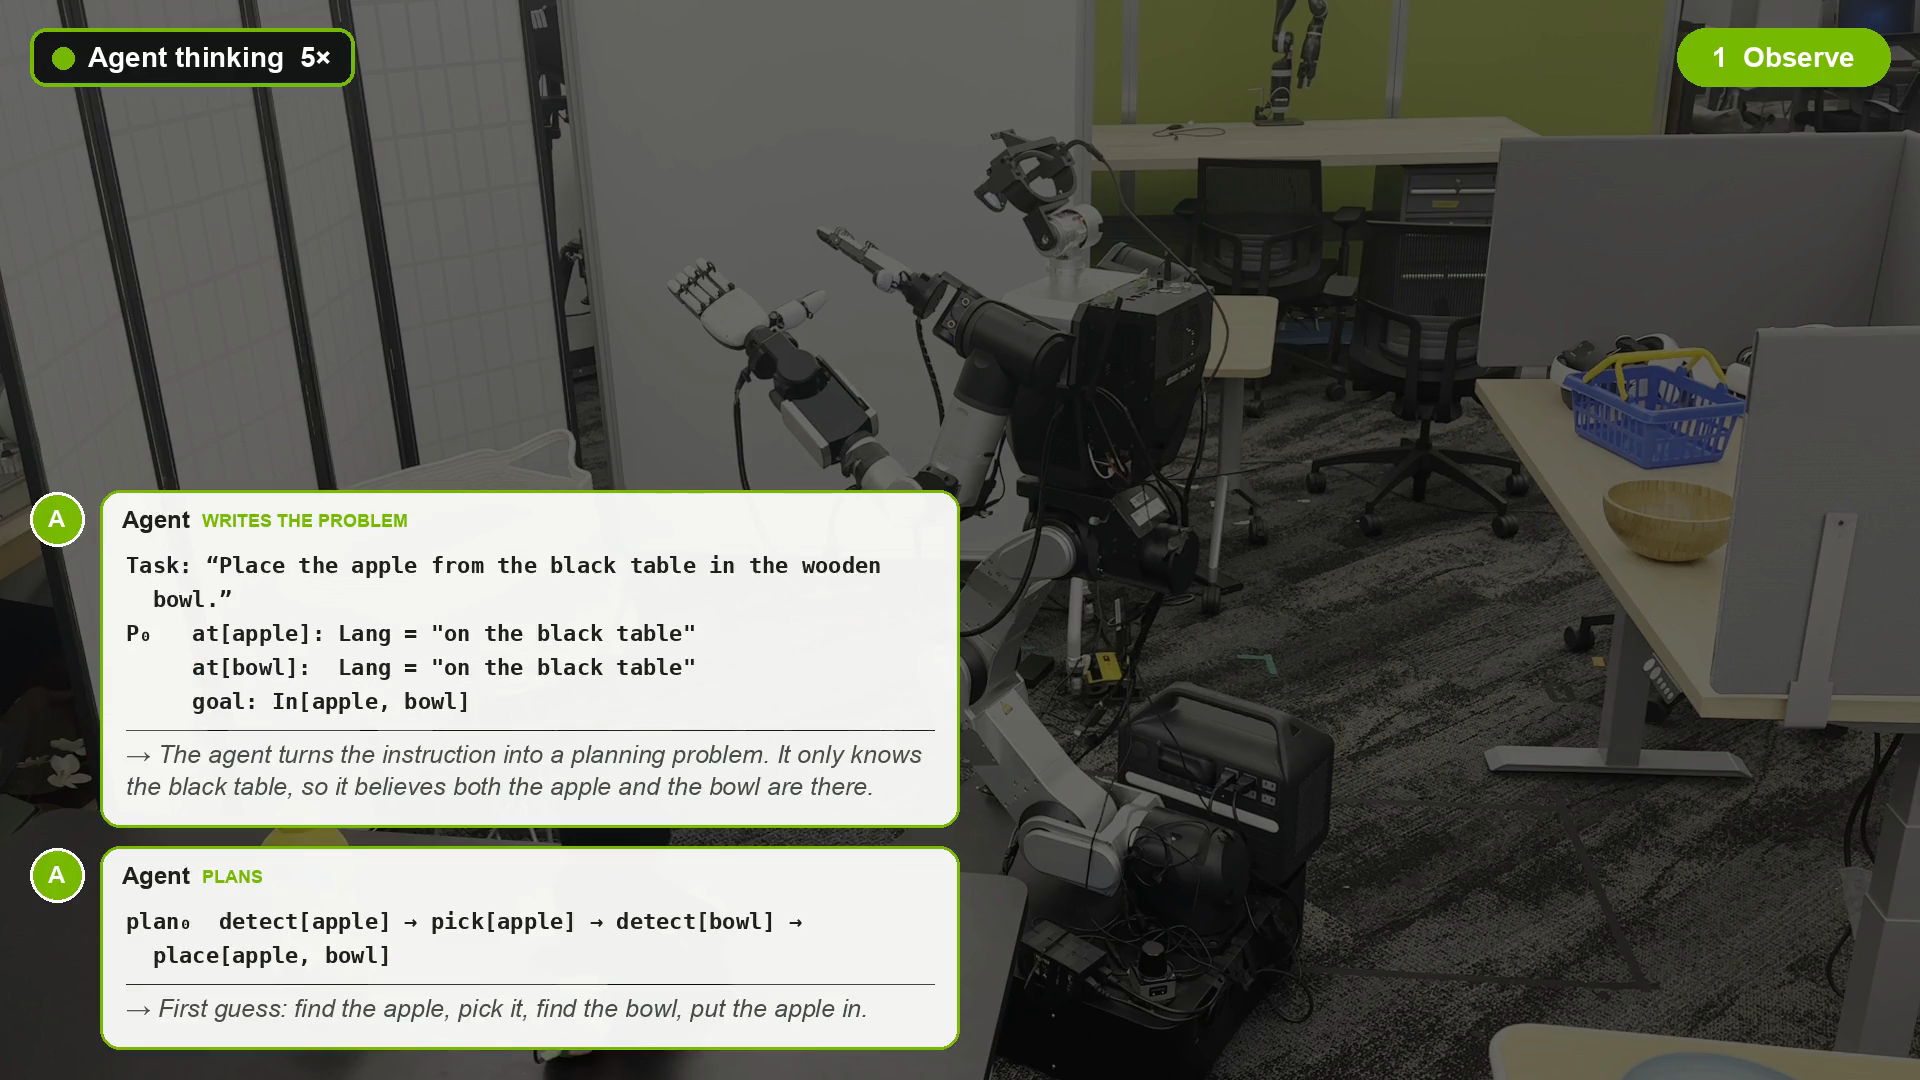
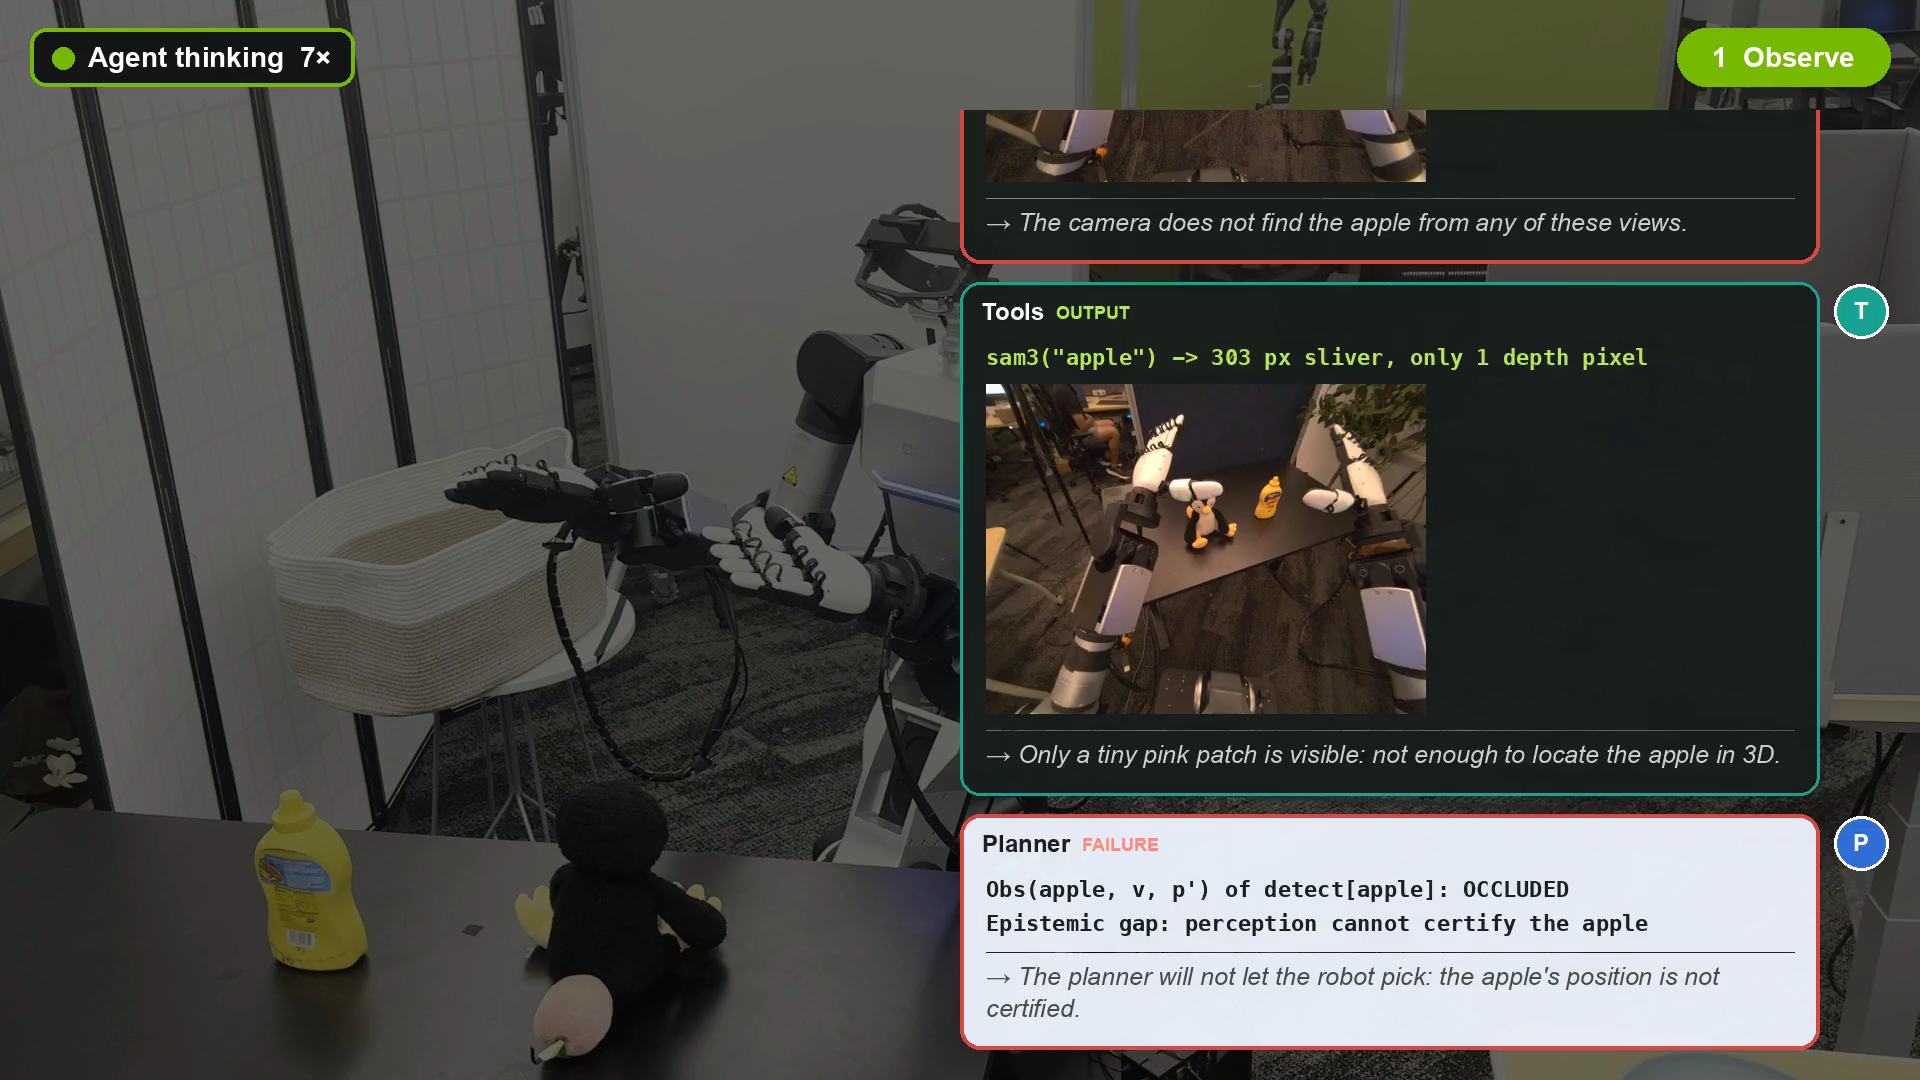
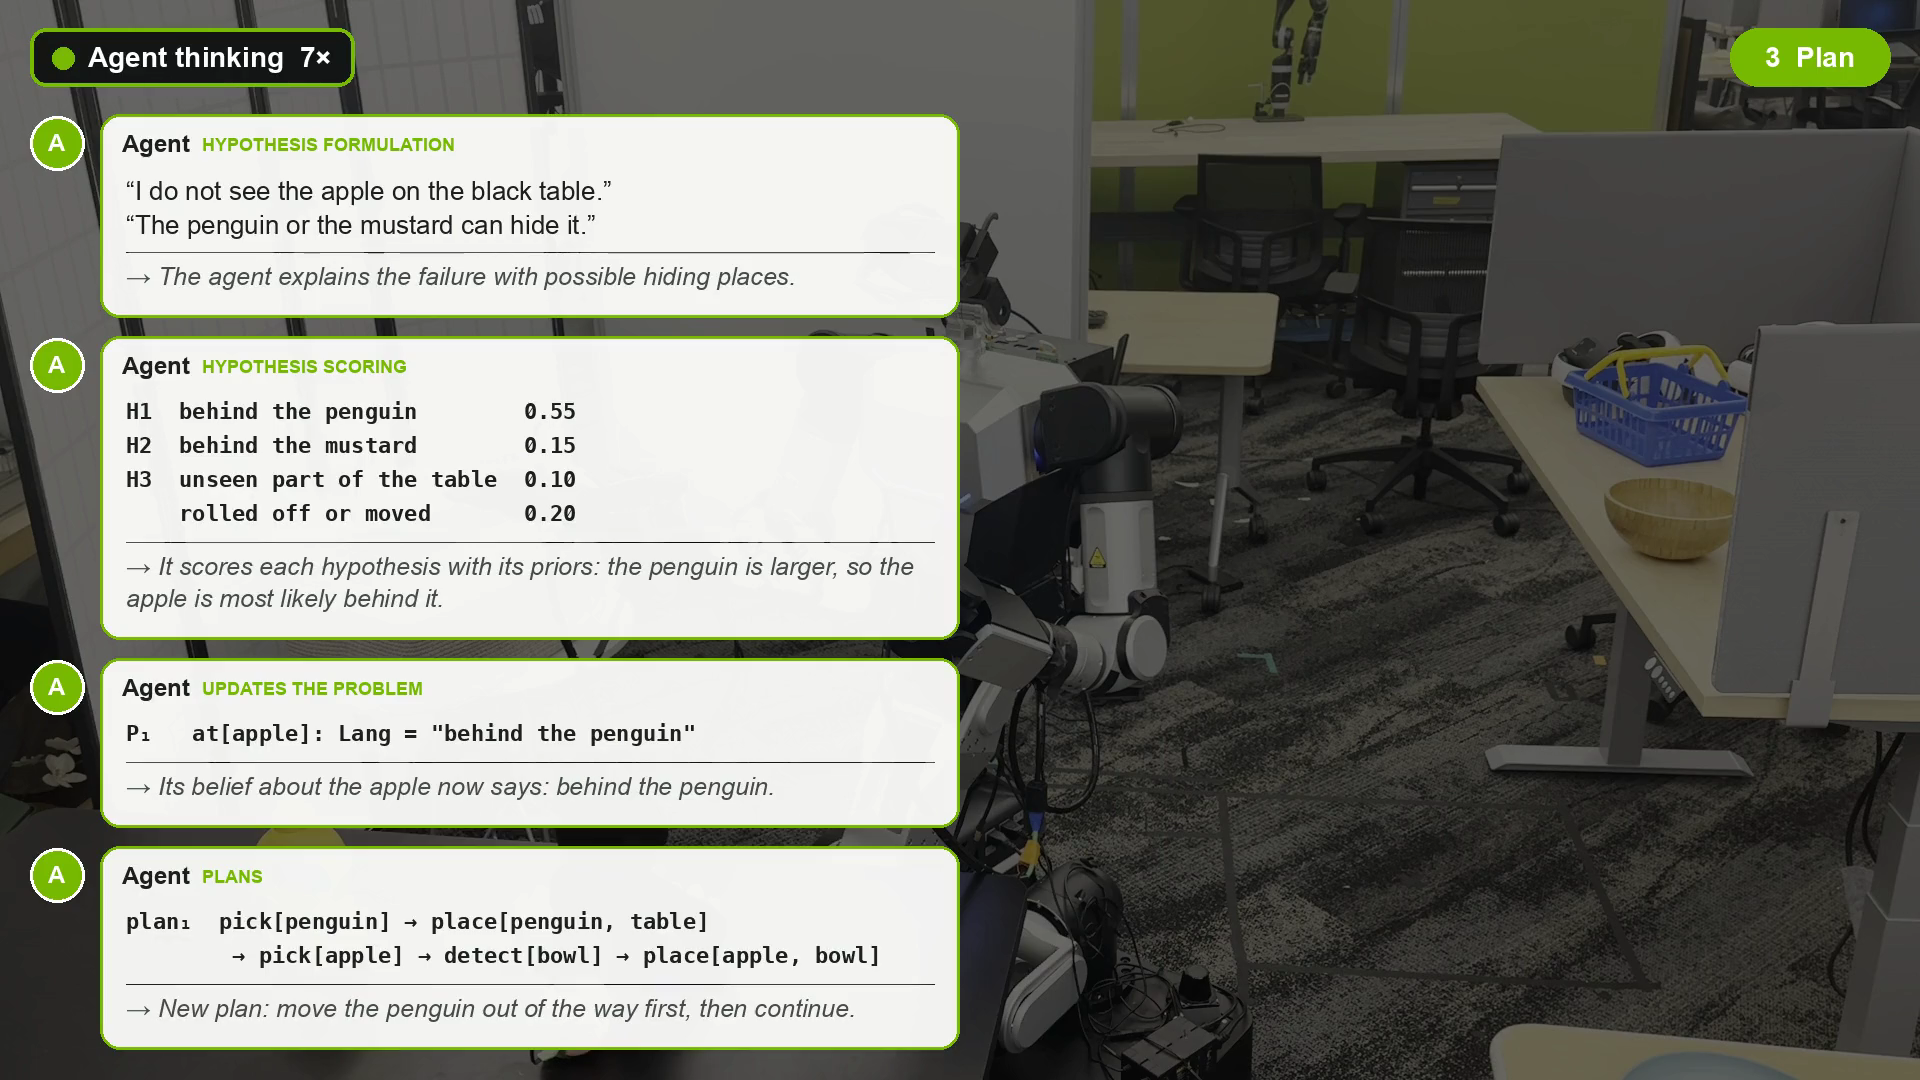
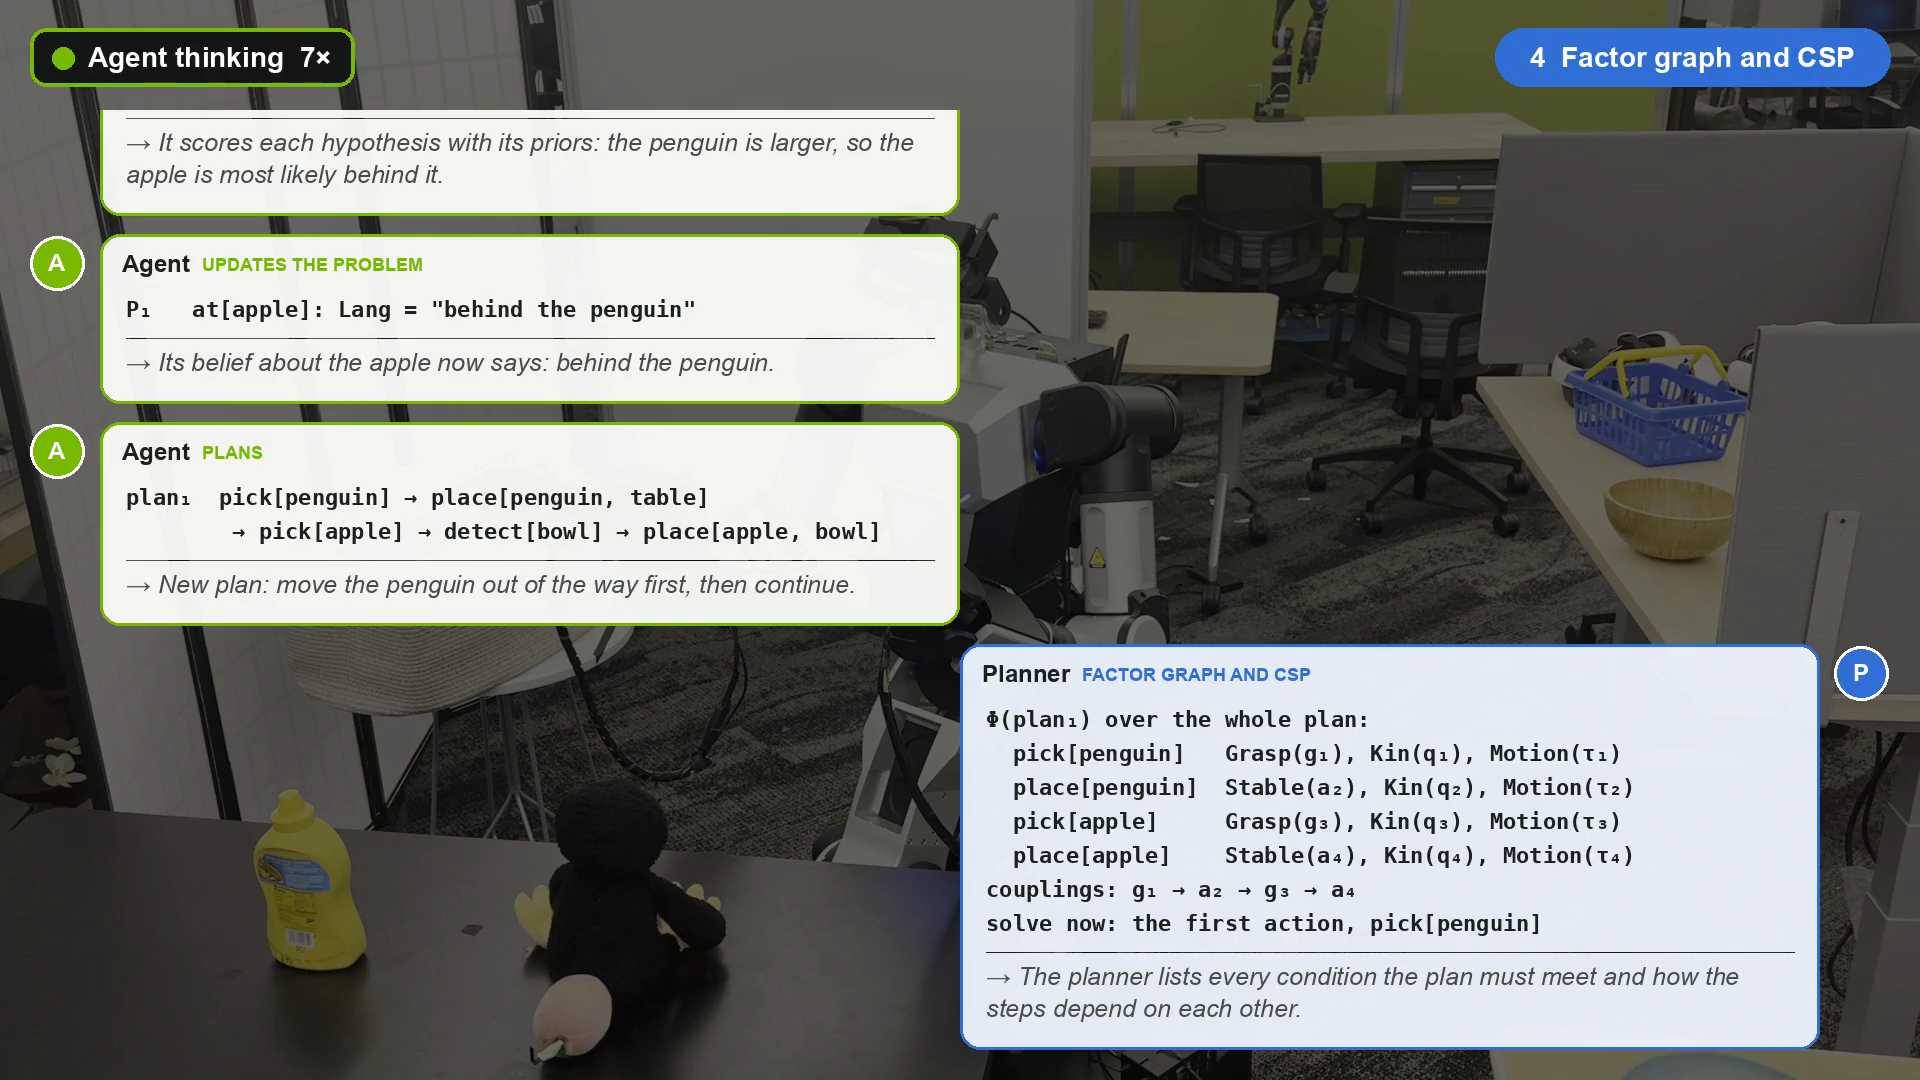
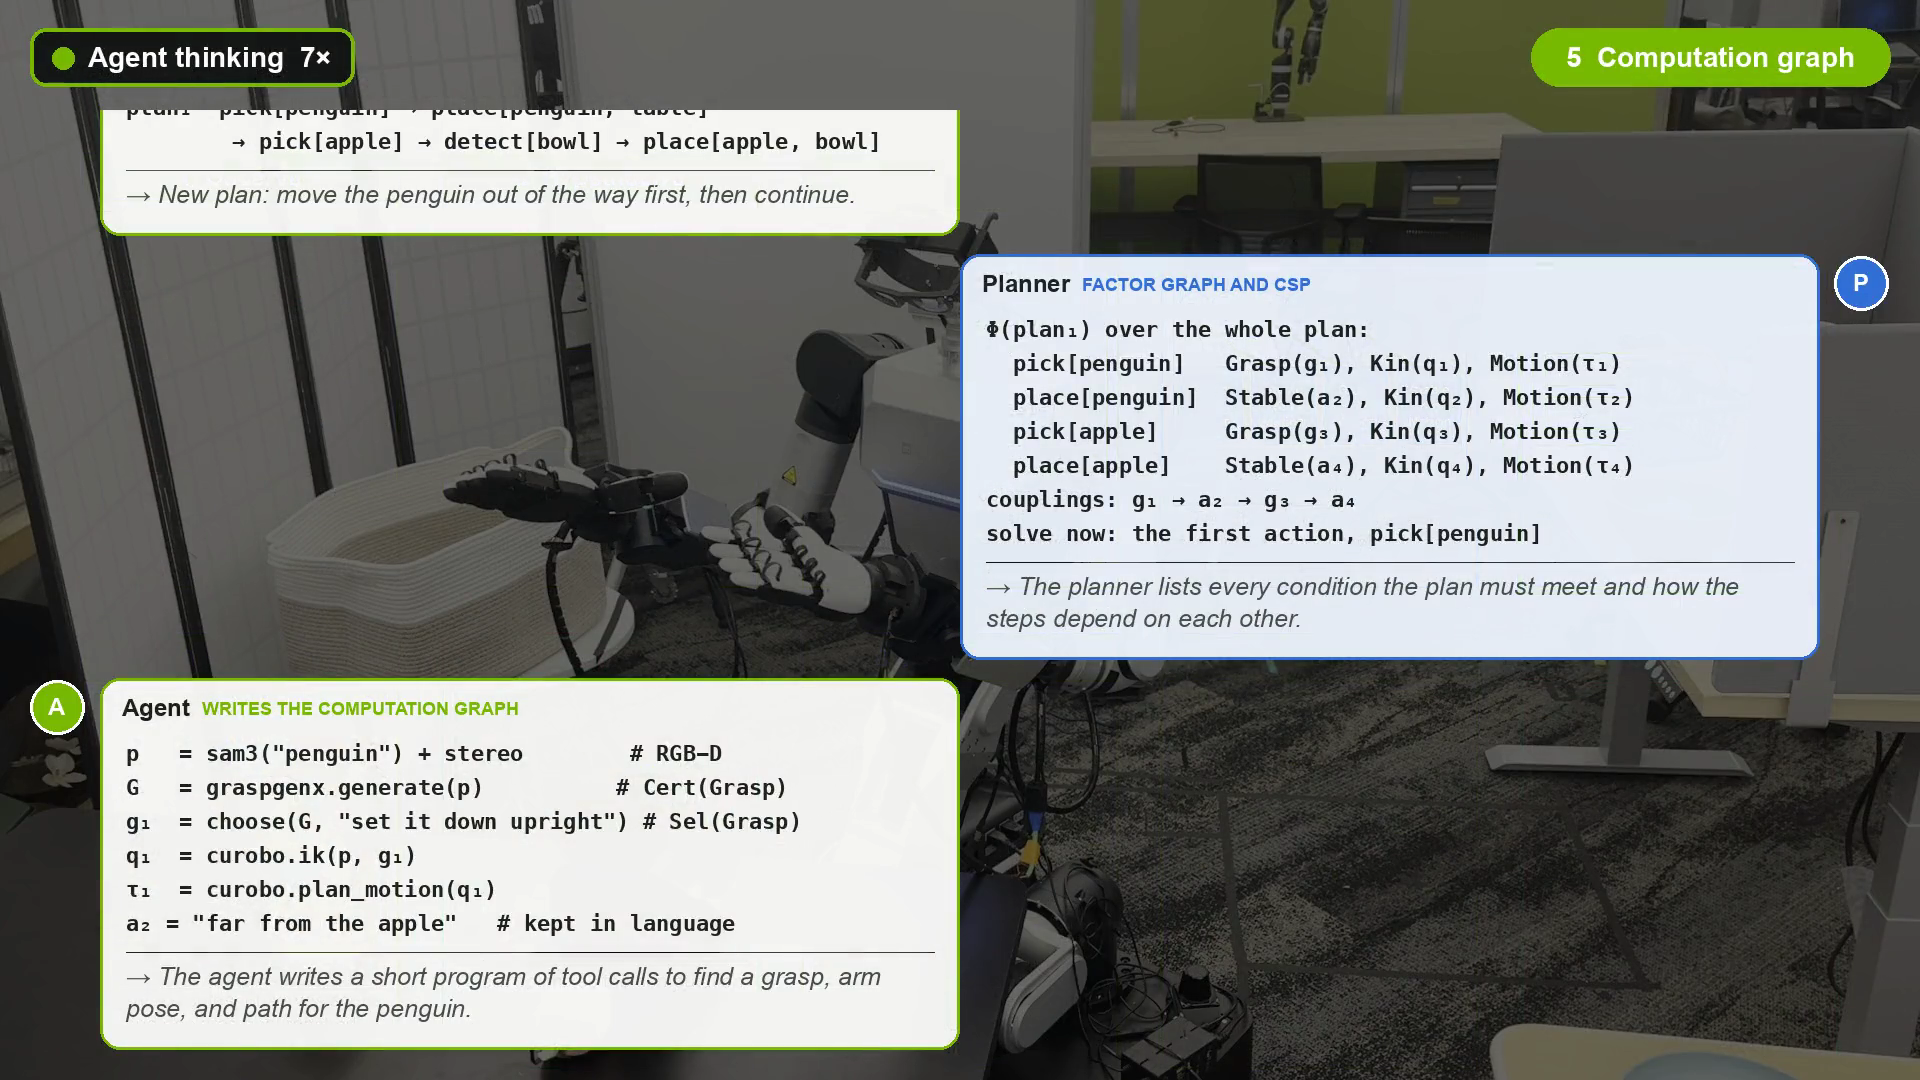
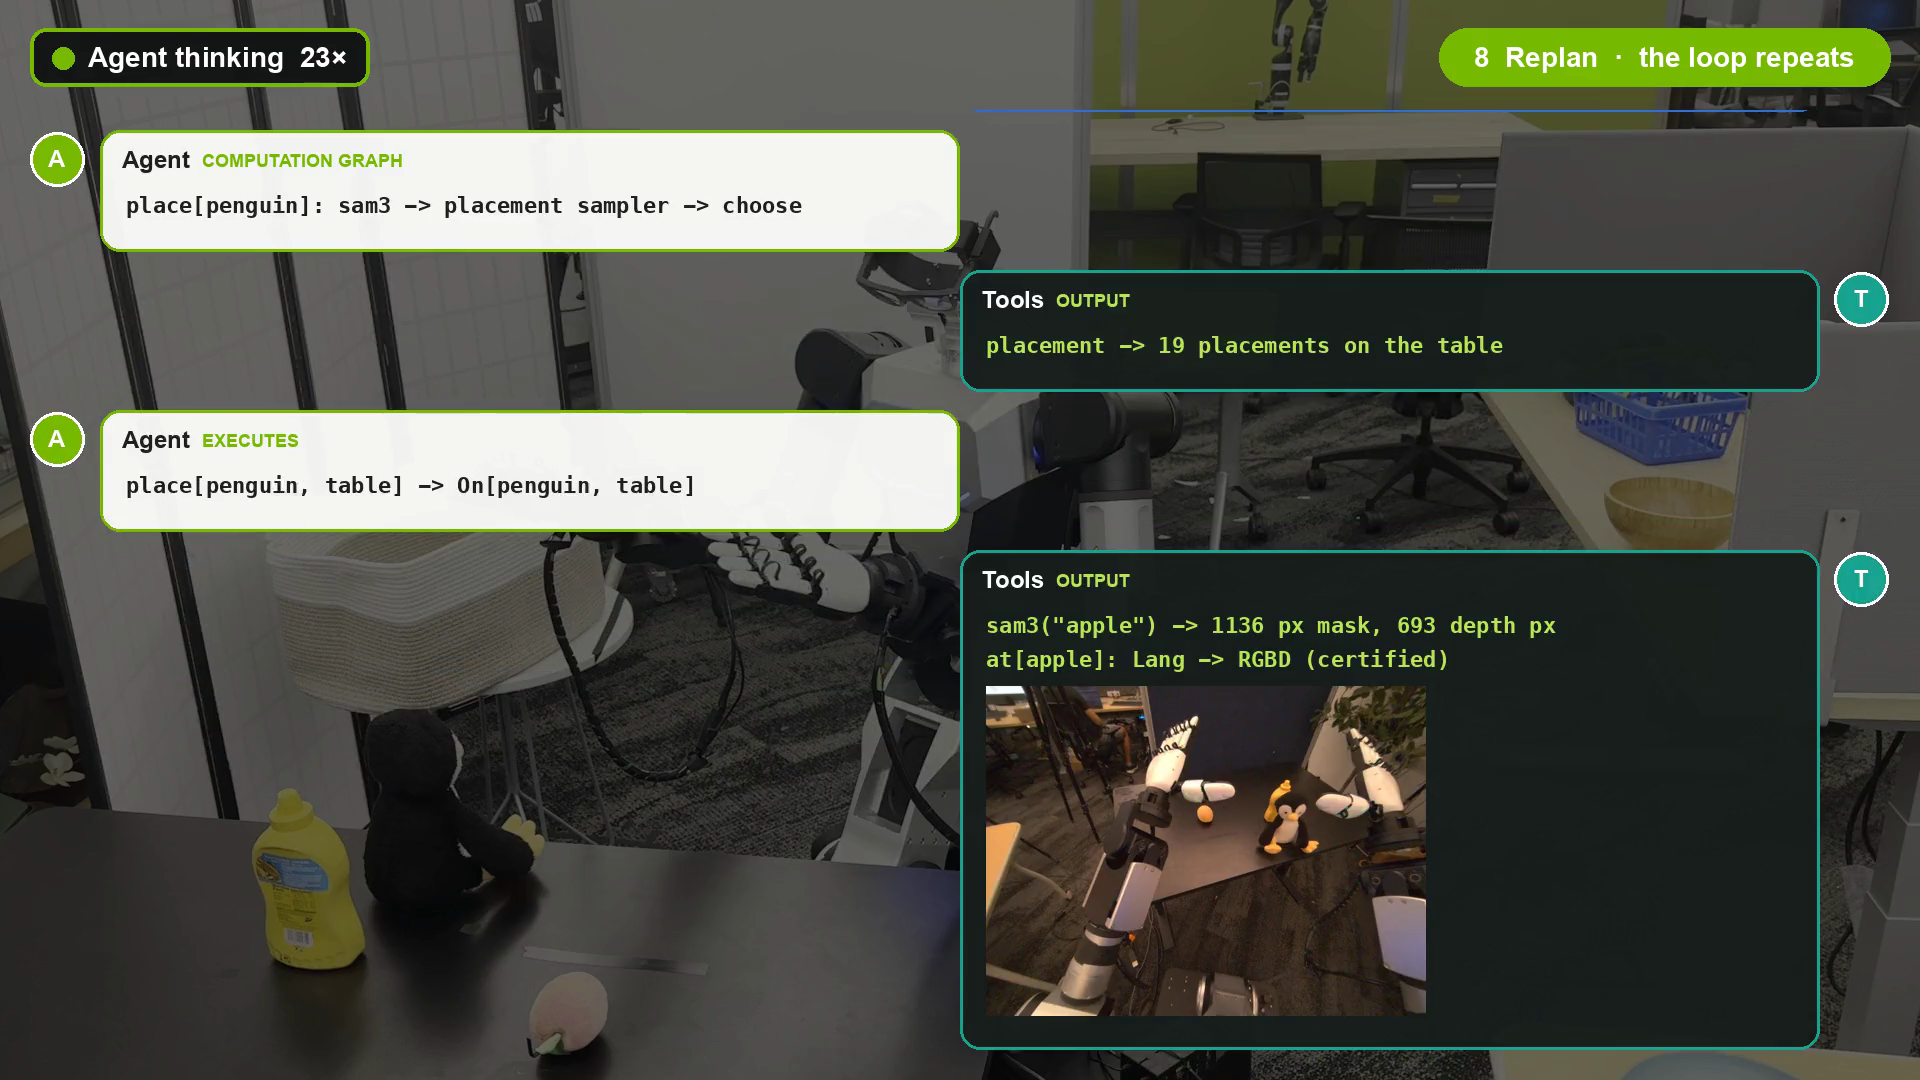
A real run, told as the conversation between the agent (left) and the planner and tools (right): place the apple from the black table in the wooden bowl, when a penguin plush hides it. The labels follow the ten steps of the planning loop; thinking and robot motion are sped up, by the factor on each badge.
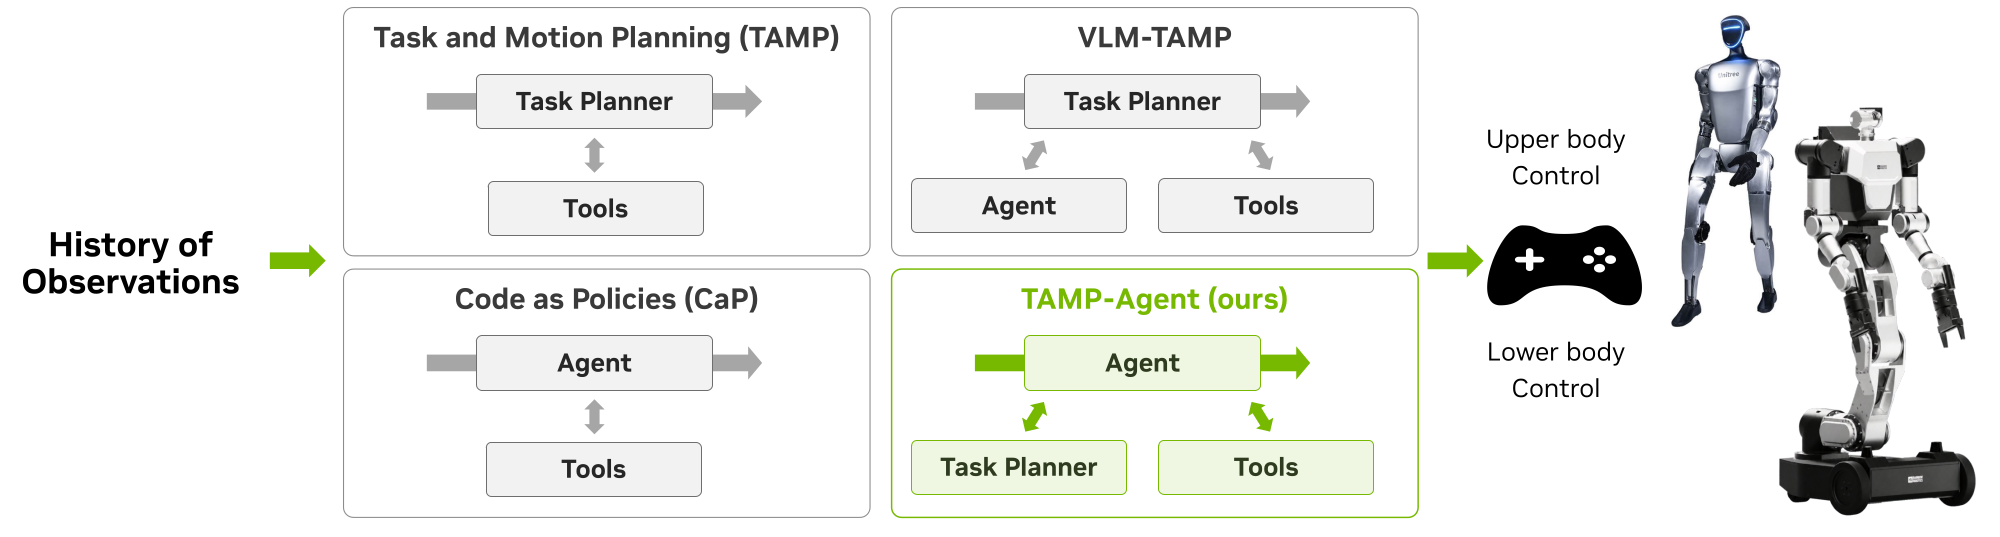
A robot in an unmapped home has to decide what to find out and how to act, often before it has seen where things are. Vision-language agents bring the priors for this, but when they call tools directly nothing declares what makes an action correct. Belief-space task and motion planning declares it, but pays for explicit distributions over the whole house and a hand-written problem.
TAMPAgent lets the agent act as the belief-space policy while its output keeps the planner's contract: parameterized actions whose constraints tools must certify before anything moves. Beliefs stay in language until a constraint needs a value from a tool.
Who orchestrates planning. TAMP solves hand-written problems with a task planner that calls the tools; VLM-TAMP lets the agent write the problem but keeps the planning pipeline fixed; Code as Policies lets the agent call tools directly and relies on execution feedback. In TAMPAgent, the agent orchestrates both the task planner, which compiles its plans into constraints, and the tools, which certify values that satisfy them.
Method
A conversation between agent and planner
TAMPAgent runs one loop. The agent writes the problem from its current belief, the planner grounds the actions, the agent plans with a hypothesis, the planner turns the plan into constraints, and the agent solves them with tools. Only then does the robot act, observe, and start again. Below, each step is shown on the run from the video.
1Write the problem
The agent turns the instruction into a planning problem: a goal and the current value of every variable it needs. Values the robot has not observed are hypotheses written in words. Here the agent only knows the black table, so it guesses that both the apple and the bowl are there, and plans to find the apple, pick it, find the bowl, and place it.
2Look, and fail to certify
The robot looks for the apple from several viewpoints. Segmentation finds nothing, then only a sliver with a single depth pixel, so the observation constraint of detect cannot be certified: the planner reports an epistemic gap and will not let the robot pick.
3Plan with a hypothesis
The agent uses its priors to rank where the object could be, and commits to the most likely explanation: the penguin plush hides it. Its plan moves the penguin out of the way before looking again.
4Build the constraint graph
The planner grounds the plan into a factor graph. The continuous choices of each action, such as the grasp, arm pose, path, and placement, become variables, and each action's preconditions become constraints over them. A variable shared by two actions couples them: the grasp chosen to pick the penguin must also let the robot set it down.
5Solve it with tools
The agent composes a computation graph of tool calls, segmentation, grasp generation, inverse kinematics, and motion planning, and runs it until every constraint of the first action has a value a tool has certified.
6Act, observe, and update
The planner accepts only when every constraint of the first action is certified. The robot executes that one action and observes, and the agent updates its belief. Once the penguin is set aside, the apple is in view: what was a language hypothesis is now a certified RGB-D estimate. The loop starts again from the first step.
The rest of the run
The same loop carries the task to the end. Two base motions toward the apple fail, so the agent picks it from where the robot stands. While carrying it, the robot searches for the bowl until perception certifies its location. No placement fits from the first stance, so the agent repositions the robot, and the apple goes into the bowl.
Sandbox
What the agent sees and writes
The agent is a coding agent, Codex or Claude Code, in a locked-down container. It has a shell, Python and a handbook, and it reaches the robot only through a gateway that forwards a fixed list of routes. Everything below is from simulation: how the sandbox is built, the handbook the agent reads, and one run of task T10, loop by loop.
1Files in its workspace
Each step is a small Python file that states what the agent believes, what it wants to do and, after running, what it achieved. Every loop starts with ranked hypotheses in plain language, and every reply is saved.
2Beliefs and plans, through the API
It writes the problem and its inventory, proposes one complete plan that the planner compiles into a CSP, and binds tool receipts to the CSP's variables. These change the planner's belief, never the robot.
3Requests for motion
It cannot move the robot directly. It asks for a grant for the exact locked step, and the planner issues one only when every constraint of that step is certified. Then it dispatches once and completes the step.
The run is task T10, where a cracker box and a mustard bottle hide the apple; the T10 video shows the full rollout. The handbook is the simulation profile's; the real robot uses the same pages, with its own parts where the robots differ.
Evaluation
Results
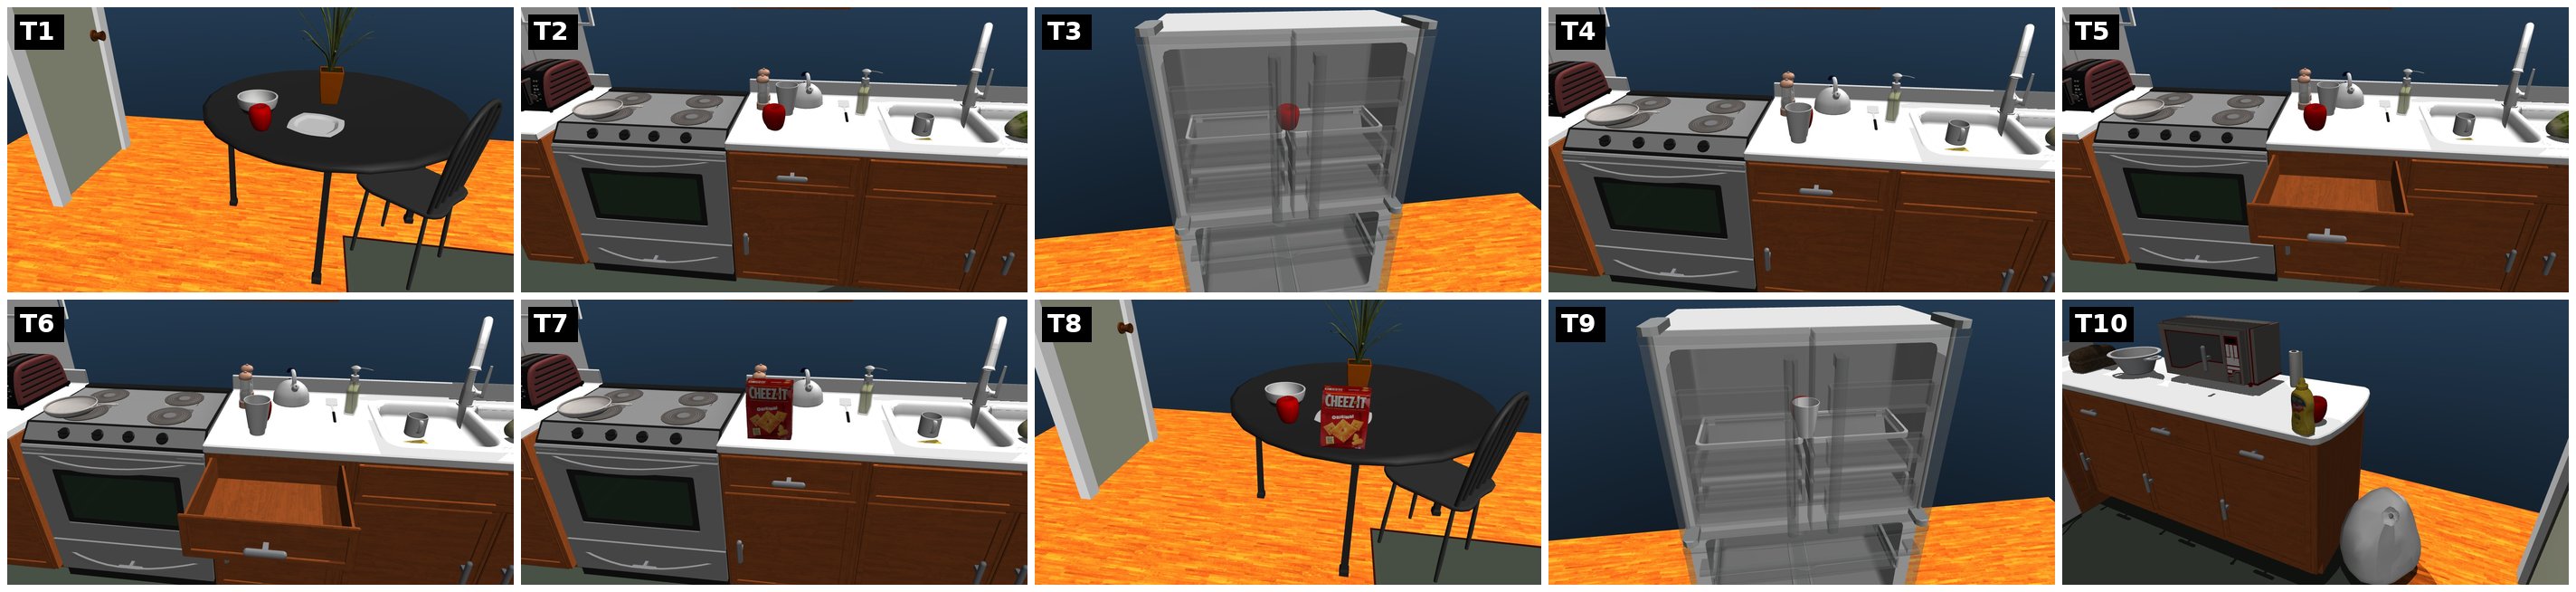
Ten simulated tasks share one instruction, serve the apple on the plate, and differ in where the apple starts and what hides or blocks it. The robot, an RB-Y1, starts facing away from the apple every time. We compare against Code as Policies (CaP), where the same agent writes code that calls the same tools without a planner, over 20 episodes per task on nine of them (T1 to T8 and T10). CaP runs GPT-6-Astra at high reasoning effort and TAMPAgent at low, and each episode has 25 minutes of simulated time. The charts are from the RB-Y1; the videos show rollouts on the RB-Y1 and on a Unitree G1.
The ten simulated tasks, close-up around the apple. In T3 and T9 the refrigerator doors are drawn translucent so the shelf is visible; in the simulation they are closed.
T1On the dining table (G1)T3Inside the fridge (RB-Y1)T4Blocked by a cup (RB-Y1)T4Blocked by a cup (G1)T5Blocked by a drawer (RB-Y1)T7Hidden behind a cracker box (RB-Y1)T8Search, then place on a cluttered table (RB-Y1)T10Clear two occluders, then carry to the table (RB-Y1)
Hypotheses and long-horizon dependencies
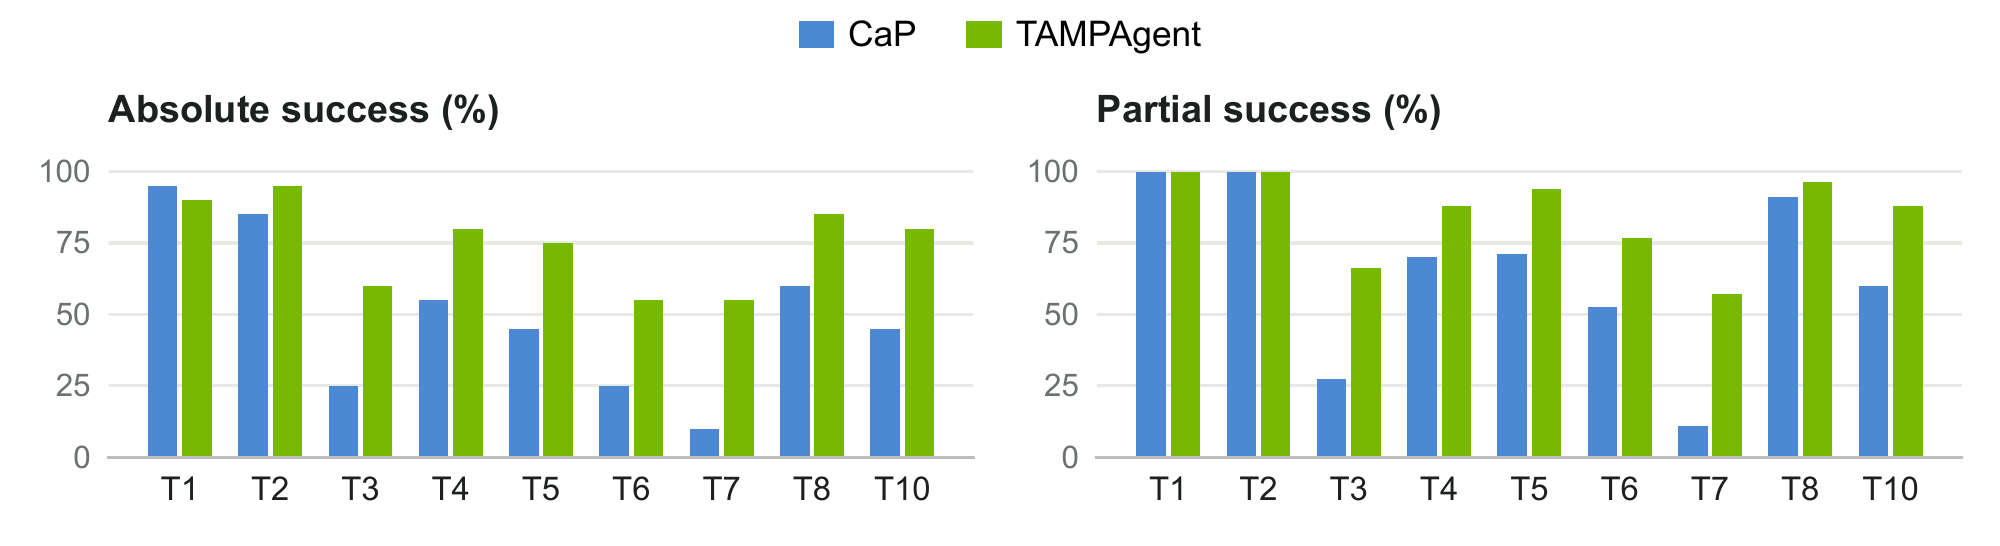
The methods are on par when the apple is in the open (T1, T2). When it is hidden or blocked (T3 to T8 and T10), TAMPAgent succeeds in 70% of episodes against 38%. Over all nine tasks, it succeeds in 75% against 49%. A plausible but infeasible plan, such as picking the apple through the cup, fails in the planner before the robot moves, and the failed constraint names what the agent must clear first.
Success over 20 episodes per task. Absolute success counts an episode only if the apple ends on the plate; partial success is the fraction of subtasks completed (find the apple, clear each blocker, pick, find the plate, place).
Fewer failures
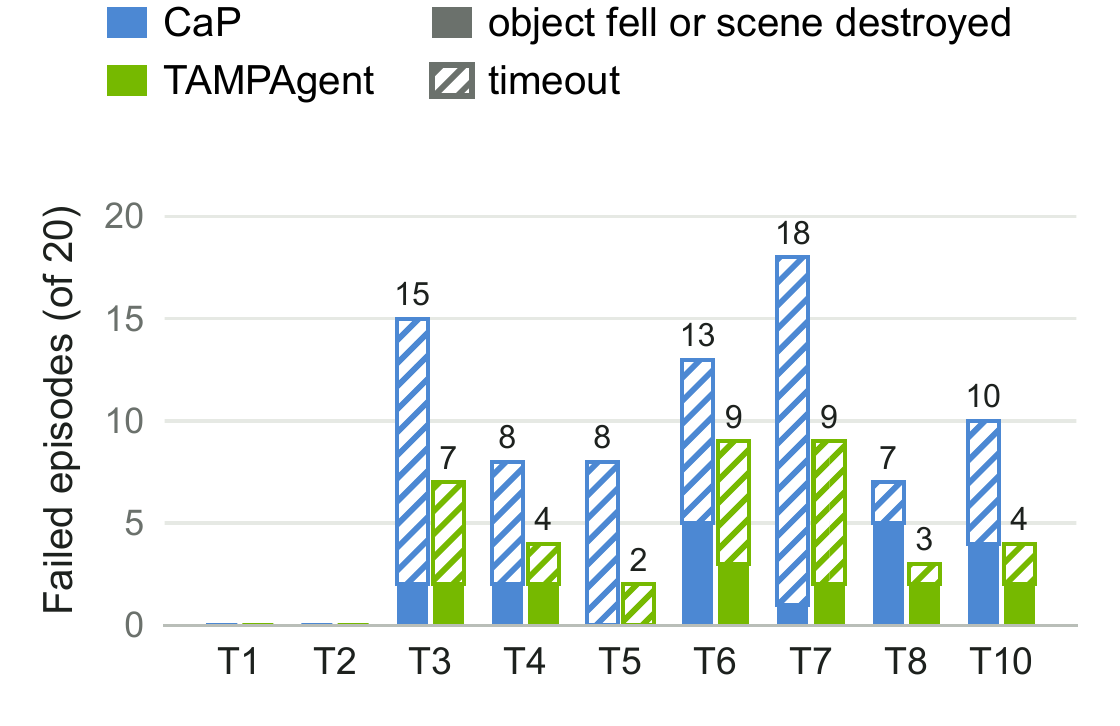
An episode fails when an object falls or the scene is destroyed, or when its time runs out. Every motion TAMPAgent executes was certified first, so over the nine tasks it drops an object or destroys the scene in 13 episodes against 19 for CaP, and it times out in 25 against 60.
Failed episodes out of 20: an object fell or the scene was destroyed (solid), and timeouts (hatched).
Fewer tokens
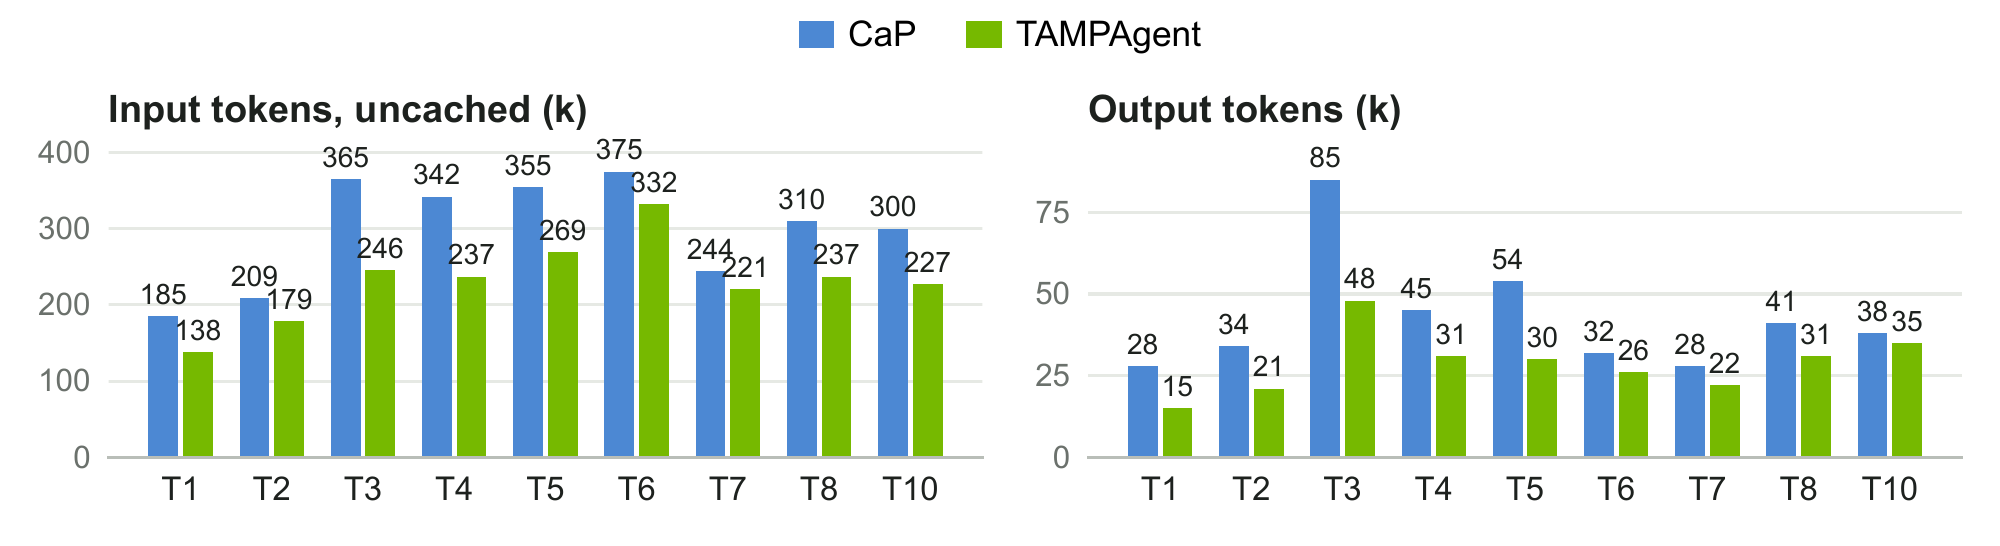
The planner keeps a compact record of the problem and its progress, so the agent reads and writes less: 22% fewer uncached input tokens and 33% fewer output tokens over the nine tasks, including those where success is on par.
Uncached input and output tokens, in thousands, averaged over the 20 episodes of each task.
On a real robot
On a real RB-Y1 in an office lab, TAMPAgent runs three categories of tasks. In simple pick and place, the robot puts an object such as a mustard bottle in a receptacle, finding both by exploring open surfaces. With an out-of-view receptacle, the robot carries the object while it searches, and plans the placement once the receptacle is certified. With a hidden object, as in the video above, the agent hypothesizes what hides the target and moves it first. Hidden objects cost the most, 973k uncached input and 127k output tokens per episode on average, against 376k and 39k for simple pick and place.
Gallery
More runs
Other real runs, on the RB-Y1 and on a Unitree G1.
RealMustard bottle into the blue basket: pick, carry while searching, place.G1Pick up the toy dog: a failed grasp check makes the agent step closer before picking.
Questions
FAQ
What does TAMPAgent guarantee?
Every constraint of an executed action was certified by a tool under the robot's current perception. The agent can still choose a poor plan, and tools can return false positives, so a certified grasp can still fail.
What are the limitations?
Skills are hand designed, though learned policies can join as tools. Cloud-hosted agents are slow: the robot is idle for more than 90 percent of an episode while the agent reasons.
Citation
BibTeX
@misc{anonymous2026tampagent,
  title  = {{TAMPAgent}: Agentic Belief-Space Planning for
            Mobile Manipulation},
  author = {Anonymous},
  year   = {2026},
  note   = {Under review}
}